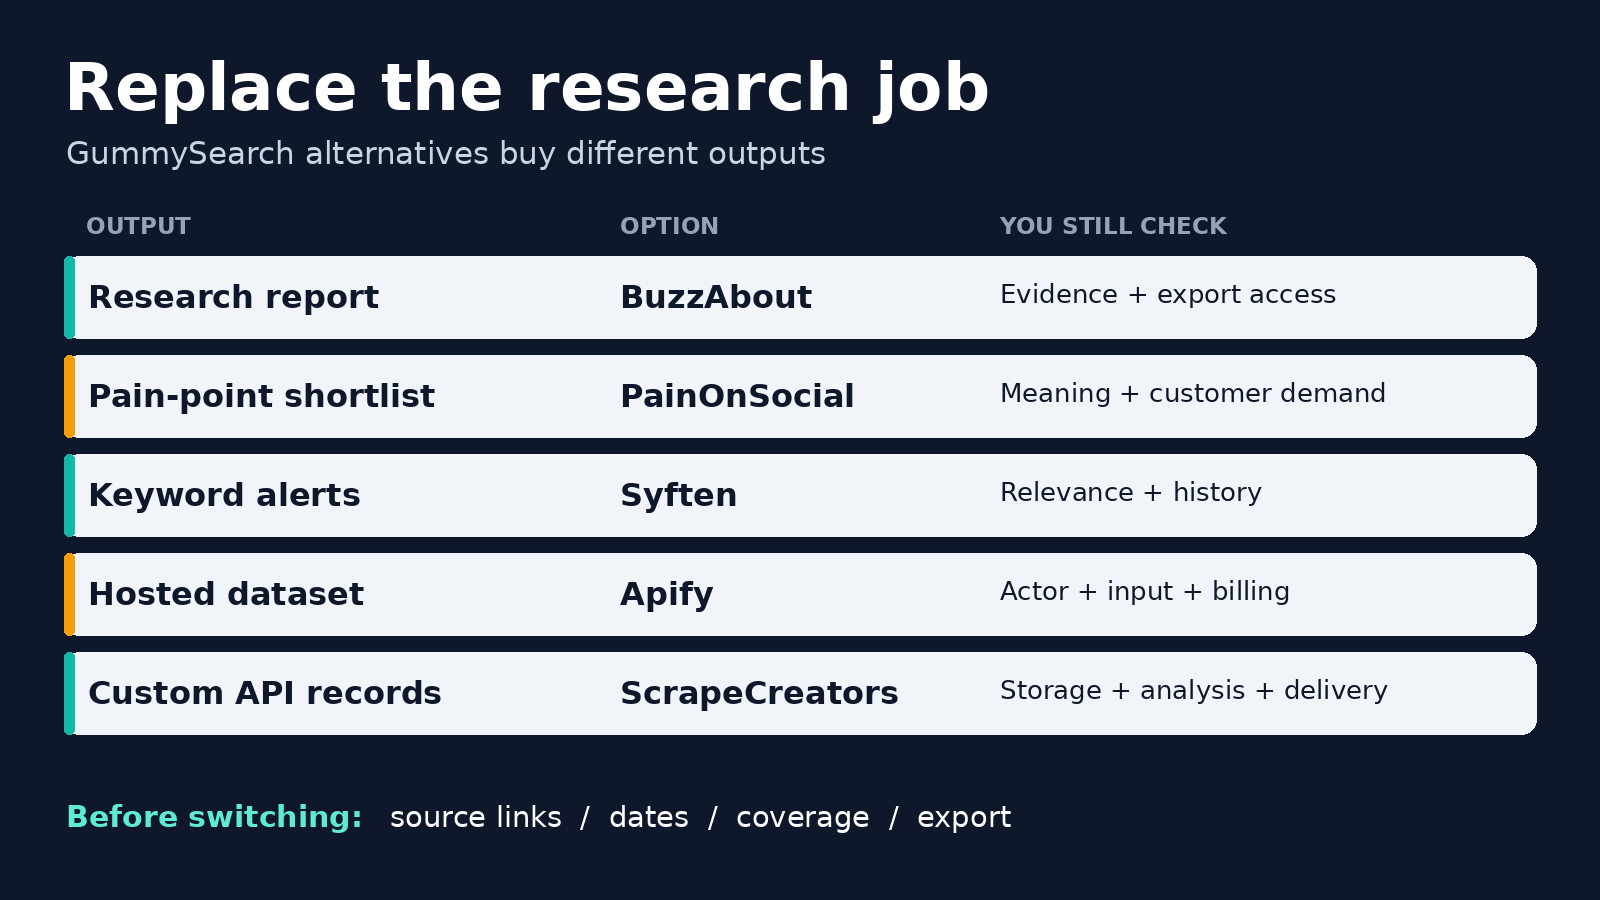
The best GummySearch alternative depends on what you used it for. Start with BuzzAbout for a finished research workspace, PainOnSocial for Reddit pain-point discovery, or Syften for keyword alerts. Choose Apify for configurable datasets and ScrapeCreators when you want to build the research workflow yourself. An alert feed does not replace audience analysis, and an API does not arrive with a finished insights dashboard.
I built ScrapeCreators, so weigh that recommendation accordingly. If you want someone else to organize the research, I would start with a workspace rather than our API.
Prices and capabilities were checked on October 31, 2026. I executed the ScrapeCreators example below, not a five-vendor performance benchmark.
What is closing, and when?
GummySearch’s official closure notice dates the business closure to November 30, 2025. New signups stopped, but existing access did not end for everyone on that day. Subscribers keep access through their billing period, up to one year. Lifetime-deal holders have access until November 30, 2026. Free users can log in to export account data or delete their account.
That distinction matters now. A tutorial showing the old interface does not mean a new customer can buy it. Nor should a generic “shuts down December 1” post replace the actual account-specific notice.
Preserve any export you can still access. I did not verify a direct GummySearch importer for the tools below. Treat this as rebuilding a research process, not moving a dashboard with one click.
Quick comparison
| Alternative | Best fit | What you receive | Purchase detail to check |
|---|---|---|---|
| BuzzAbout | Research across social sources | Workspace with patterns and supporting mentions | Pro is $178/month; audience research and CSV/PDF export are not included in Starter |
| PainOnSocial | Finding recurring Reddit frustrations | Ranked pain points, evidence links, and solution ideas | Starter is $19/month after its trial; 20 scans/month, up to two subreddits/scan |
| Syften | Continuing keyword tracking | Matches delivered into an alert workflow | Entry is $29.95/month; archive depth and integrations depend on plan |
| Apify Reddit Scraper Lite | Configuring a collection job without writing the scraper | Dataset records and downloadable formats | Free-account events: $4 per 1,000 stored results, plus $0.02 per Actor start per GB |
| ScrapeCreators | Owning the evidence model and analysis | Public search and thread JSON for your application | $47 buys 25,000 prepaid credits; these Reddit requests normally cost one credit each |
These prices buy different things. A scan can include AI interpretation. A stored result is a dataset billing object. A request can return several records, or an empty result. None is a fair substitute for “cost per validated customer problem.”
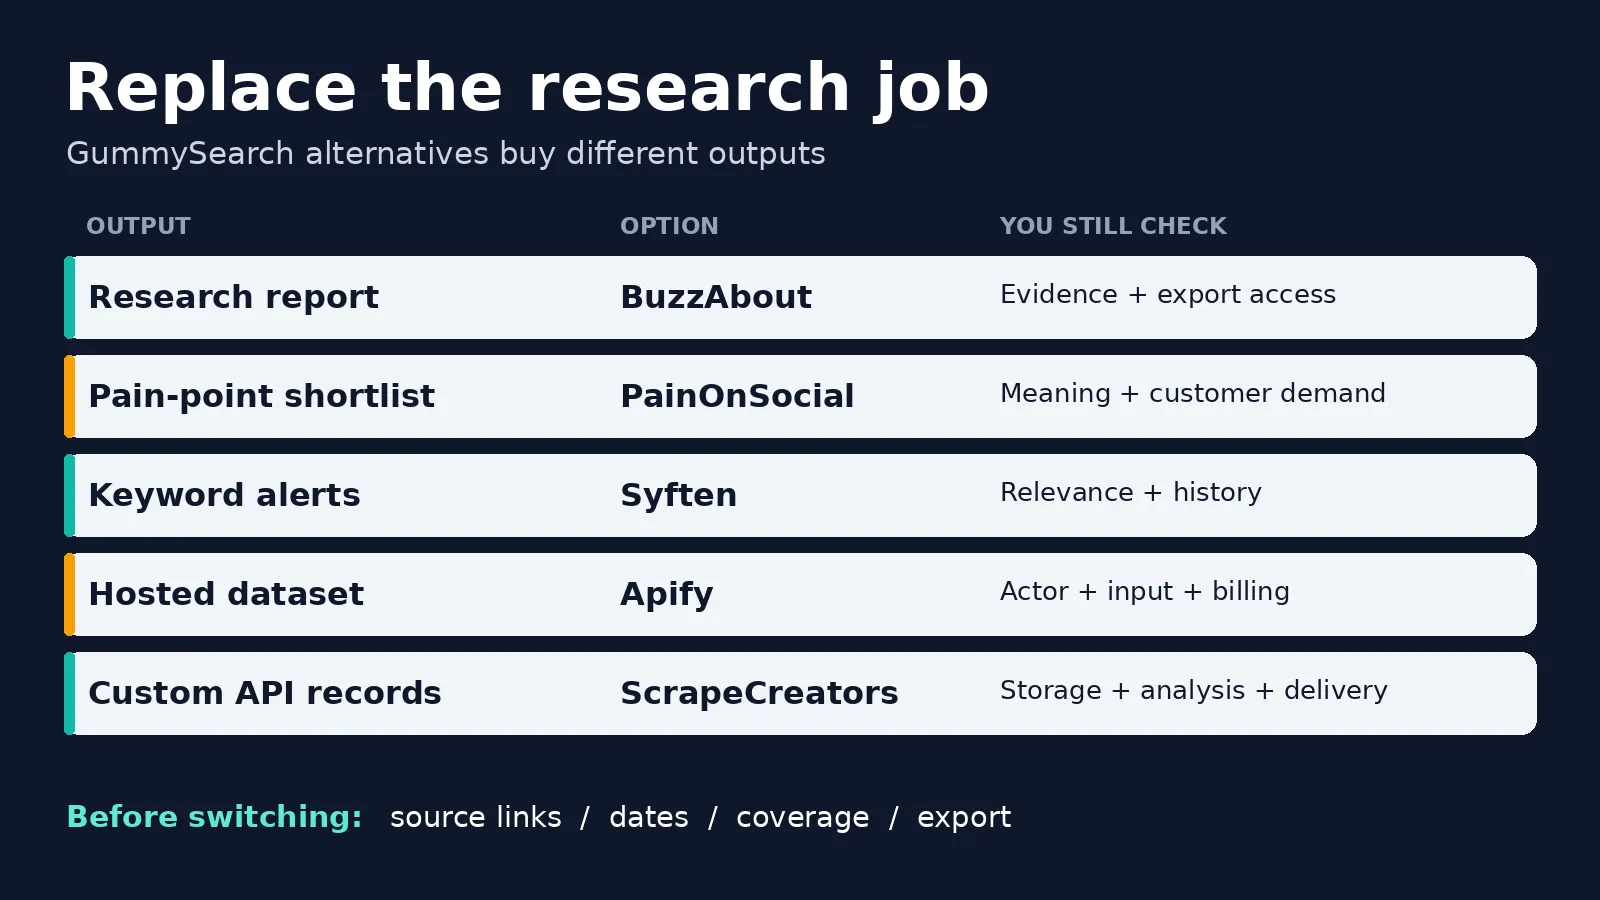
1. BuzzAbout for a finished research workspace
BuzzAbout is the first option I would examine if your team wants research without maintaining a collector. Its product page describes social-source research with patterns backed by mentions. Use a workspace like this when the handoff is a report that another person can inspect, not a raw JSON response.
Watch the feature gates. The current pricing comparison puts audience research and CSV/PDF export on Pro and above. Starter is $98/month, but it does not include those features. Pro is $178/month with 5,000 monthly credits, three seats, and up to 1,000 mentions per research. API access starts on Business at $450/month.
Annual Pro costs $1,780 paid upfront. That is a different commitment from paying $178 each month. Included credits reset monthly. Credits also pay for different actions, including mentions and AI work, so do not read 5,000 credits as 5,000 completed reports.
Choose another option if you mainly need cheap keyword notifications or raw records inside an existing application. Before buying, ask for a sample report from your actual communities. Check whether a promising pattern links to several relevant conversations rather than one memorable complaint.
2. PainOnSocial for Reddit pain-point discovery
PainOnSocial is the narrower choice for a founder asking, “What problems keep coming up in these communities?” Its current workflow starts with selected subreddits and returns ranked pain points, quotes, source permalinks, and suggested solutions.
Starter costs $19/month after a seven-day trial. It includes 20 scans per month, up to two subreddits per scan, one weekly topic watch, and up to ten evidence items per pain point. Professional is $49/month with 300 scans and up to five subreddits per scan. The comparison lists 7-, 30-, and 90-day analysis windows.
A scan limit, community limit, and time window answer different questions. Check all of them before expecting a broad historical market study. The page’s AI score is also a product-generated ranking, not independent proof that someone will pay for the proposed solution.
Choose another tool if the core job is cross-platform reporting or an immediate alert every time a keyword appears. I would use the ranked problems to plan interviews, then ask people about their current workaround and spending. I would not turn a high pain score directly into a revenue forecast.
3. Syften for ongoing keyword alerts
Syften fits the part of GummySearch that helped you notice new conversations. Its pricing and feature page separates tracked filters, daily match allowances, and archive access. That makes it a more natural fit for “tell me when this comes up again” than for rebuilding a pain-point research board.
Entry is $29.95/month, with three community filters, 100 community results per day, and seven days of archive search. Standard is $49.95/month with 20 community filters and a 30-day archive. Pro is $119.95/month and adds webhooks, MCP, and full available archive history. Full available history still varies by source; it does not promise every Reddit post ever written.
Do not confuse access to your account matches with unrestricted archive querying. The page specifically puts archive API search on Pro. Check the documentation for the relevant integration and history boundary.
Choose Syften when someone will review and act on the matches. Choose a research workspace instead if you expect the software to organize a market study. Our separate Reddit monitoring comparison covers that notification-focused buying decision in more detail.
4. Apify for configurable research datasets
Apify is useful when you want to configure collection in a hosted interface and take away a dataset. The specific option reviewed here is Trudax’s Reddit Scraper Lite, not every Reddit Actor in the marketplace.
Its input schema accepts Reddit URLs or search terms. It exposes limits for stored items, posts, and comments, plus community and search settings. That suits a buyer who wants control over collection without maintaining the scraper code.
One important input trap: the README says supplied startUrls take precedence over search parameters. If you intend a keyword search, remove the start URLs rather than assuming both inputs combine. The schema also leaves includeMediaLinks false by default; that option enables additional post details, including votes and comment counts. Inspect the actual output before building an engagement ranking.
Use the current event-pricing tab, not the README’s older Starter-plan recommendation. It lists $4 per 1,000 stored results on the free account, falling to $3.40 on Business, plus $0.02 per start per GB. Platform usage is included for this Actor. Do not add a second generic compute charge or treat the Business rate as the free-account price.
The separate trudax/reddit-scraper listing is marked deprecated; Lite is a different listing. Check the exact Actor ID before copying an old tutorial. I did not execute this Actor, and a dataset does not include GummySearch’s audience taxonomy or prove complete thread coverage. The broader Reddit scraper guide covers other collection approaches.
5. ScrapeCreators for your own evidence pipeline
ScrapeCreators fits a developer who wants to decide how research is stored and interpreted. Our Reddit API provides search and thread data. It does not provide a finished replacement for saved audiences, AI pain scoring, research reports, or alert delivery.
The search reference distinguishes post search from comment search. Post search has sort, timeframe, and after pagination. Comment search uses filter=comments; do not assume the post timeframe also filters comments. A thread request is a separate call.
Current credit pricing starts with 100 free credits and a $47 pack containing 25,000 credits that do not expire. Search and thread calls normally cost one credit each. The successful calls in this example charged one each. Successful empty searches can also charge; do not budget solely by the number of rows you keep.
You supply scheduling, storage, deduplication, categorization, and review. If that sounds like unnecessary work, choose one of the finished tools above. If you already have a database and analysis process, create an account and test one community before expanding.
A small executed research example
The following Python uses only the standard library. It collects one search page, selects one post from the intended community, then retrieves that thread. It saves source-linked evidence and deliberately leaves theme empty. It does not invent a pain score or automatically reply to anyone.
import json
import os
import urllib.parse
import urllib.request
from datetime import datetime, timezone
from pathlib import Path

observed_at = datetime.now(timezone.utc).isoformat()
responses = []

def get(path, params):
    request = urllib.request.Request(
        "https://api.scrapecreators.com" + path + "?" + urllib.parse.urlencode(params),
        headers={"x-api-key": os.environ["SCRAPE_CREATORS_API_KEY"]},
    )
    with urllib.request.urlopen(request, timeout=60) as response:
        body = json.load(response)
    if body.get("success") is not True:
        raise RuntimeError("API did not return success")
    responses.append(body)
    return body

search = get("/v1/reddit/search", {
    "query": "subreddit:Notion calendar", "filter": "posts",
    "sort": "new", "timeframe": "month",
})
posts = [p for p in search.get("posts", [])
         if p.get("id") and p.get("subreddit", "").lower() == "notion"]
if not posts:
    raise RuntimeError("No matching community records; stop rather than invent evidence")
post = posts[0]
source_url = "https://www.reddit.com" + post["permalink"]
thread = get("/v1/reddit/post/comments", {"url": source_url})
if thread.get("post", {}).get("id") != post["id"]:
    raise RuntimeError("Returned thread identity differs from the selected post")

rows = [{"kind": "post", "id": post["id"], "source_url": source_url,
         "observed_at": observed_at, "created_at": post.get("created_at_iso"),
         "text": post.get("title", "") + "\n" + post.get("selftext", ""),
         "theme": None}]
seen = set()
def collect(comments):
    for comment in comments:
        cid, text = comment.get("id"), comment.get("body")
        if cid and cid not in seen and text and text not in ("[deleted]", "[removed]"):
            seen.add(cid)
            rows.append({"kind": "comment", "id": cid,
                         "source_url": comment.get("url") or source_url,
                         "observed_at": observed_at, "text": text, "theme": None})
        replies = comment.get("replies") or []
        collect(replies.get("items", []) if isinstance(replies, dict) else replies)
collect(thread.get("comments", []))
Path("research-evidence.jsonl").write_text(
    "\n".join(json.dumps(row, ensure_ascii=False) for row in rows) + "\n"
)
# Local audit files, not a public export of your account balance.
Path("research-responses.json").write_text(json.dumps(responses, indent=2))
print(json.dumps({"saved_rows": len(rows), "requests": len(responses),
                  "credits_charged": sum(r.get("credits_charged", 0) for r in responses),
                  "more_search_pages": bool(search.get("after")),
                  "public_comment_total": thread["post"].get("num_comments")}))
My October 31 run saved four evidence rows: one post and three comments. It made two requests and charged two credits. The thread’s public comment counter was four, which was not the number of comments fetched. More search pages remained. This was a bounded sample, not a full community export.
Separate pagination checks returned seven posts on each of two pages, with no overlapping IDs. However, the first page’s requested month window included a post dated February 3, 2025. A successful search is not proof that a requested date boundary was honored. Validate returned dates before making a “this month’s problems” claim. The short example above preserves the observation without claiming a validated monthly sample.
The first selected thread was a general Notion automation question, not proof of calendar purchase intent. Someone still needs to read the evidence and reject weak matches. Retrieval, interpretation, and customer validation are separate steps.
A replacement checklist that survives the next switch
Use one small acceptance set before buying a year of access:
- Keep your research definition. Save community names, inclusion rules, exclusions, and the decision the research should inform. A vendor’s category labels should not become your only way to describe a market.
- Keep the source trail. Preserve permitted evidence, stable IDs, source links, collection dates, and analysis notes separately. Respect source terms and your retention requirements; a public link is not blanket permission for every downstream use.
- Test an old and a new conversation. Check actual dates, missing comments, edited material, and history limits. A replacement cannot recover your old saved annotations unless a real migration path exists.
- Ask for the needed output. Open the CSV, follow evidence links, or inspect the JSON. A feature named “AI research” does not tell you which of those you can take away.
- Separate discovery from outreach. Finding an unanswered question does not authorize automated promotion. Keep human review and community rules in the workflow.
The original GummySearch customer-discovery demo shows why source conversations and saved research mattered. A later DIY research walkthrough also makes source IDs central to reviewing AI-created groups. Neither proves that an API call recreates a research product.
A public discussion about research-process lock-in reinforced the importance of keeping evidence and categories portable. It includes vendor promotion, so I used it as a qualitative prompt for the checklist, not a representative customer survey or endorsement.
Questions before you switch
What is the closest GummySearch alternative for audience research?
Start by evaluating BuzzAbout’s research workspace or PainOnSocial’s Reddit-focused analysis. They organize findings for you. Syften buys monitoring; Apify and ScrapeCreators buy collection infrastructure. Decide which missing job matters before comparing prices.
Can I keep using my existing GummySearch account?
Check your account against the official notice. The business closure, an existing subscription’s end date, and the lifetime-deal access deadline are different. Do not assume continued login means new subscriptions remain available.
Can I rebuild GummySearch with an API and an AI model?
You can build a narrower workflow, as the example demonstrates. A full replacement still requires community selection, history, source checks, analysis, saved research, and delivery. Ask the model to propose themes with supporting IDs, then verify that those IDs exist and the evidence actually supports each theme.
Which option should I choose if I do not code?
Choose BuzzAbout or PainOnSocial for organized research, Syften for alerts, or Apify’s interface for configurable datasets. Choose ScrapeCreators only if you are comfortable building the missing workflow or have someone who will maintain it.