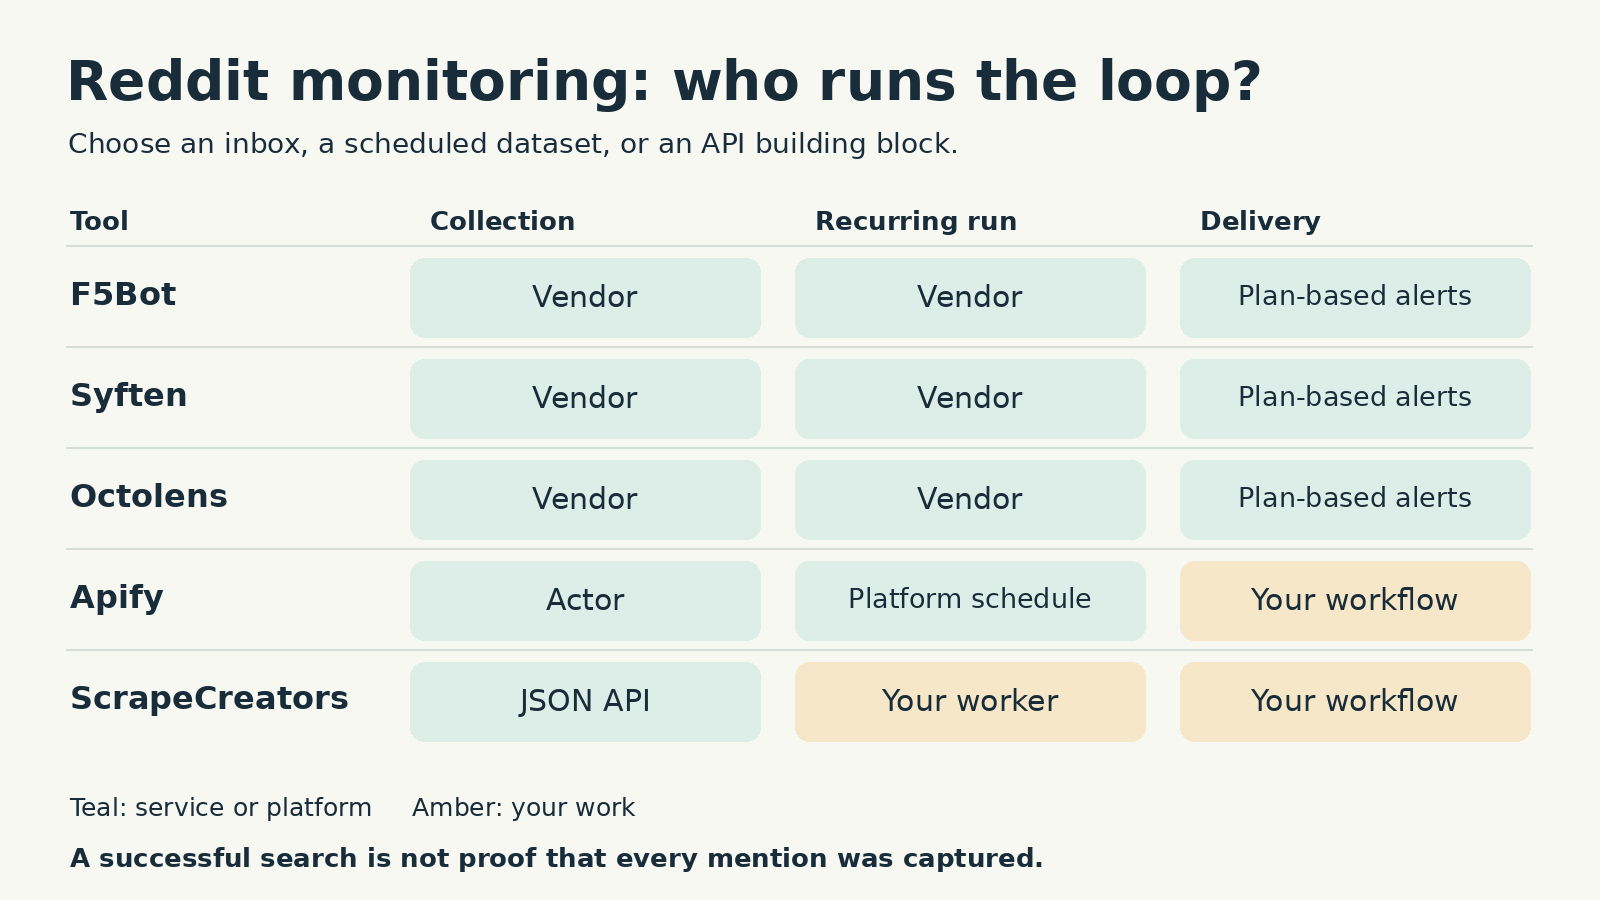
For Reddit keyword monitoring, choose F5Bot for simple email alerts, Syften for precise filters, or Octolens for a shared listening workflow with an API and webhooks. Choose Apify when you want scheduled datasets. Use ScrapeCreators only if you want to build the monitoring loop yourself. A search API is a data source, not a finished alert service, and a keyword match is not proof of buying intent.
I run ScrapeCreators. It is not my first recommendation if you just want an email when someone mentions your product. I checked the linked product pages, plan limits, and prices on October 22, 2026. I also ran public Reddit requests and the Python example below. I did not benchmark the other services or measure their alert latency.
Quick comparison
| Tool | Choose it when | Price and billing unit checked today | What you still need to check |
|---|---|---|---|
| F5Bot | You want a small email alert setup | Personal-use free tier; Silver is $9.99/month | Business use, common words, alert caps, and delivery tier |
| Syften | You need detailed matching rules for community conversations | Entry $29.95/month; Standard $49.95/month; PRO $119.95/month | Filter count, daily results, archive access, and integration gates |
| Octolens | A team wants filtered mentions, reporting, and integrations | Pro $199/month billed monthly, or $159/month billed annually | Refresh interval, mention quota, and overage settings |
| Apify Reddit Scraper Lite | Your output should be a recurring dataset | Stored-result charges plus an Actor-start event; rate depends on platform plan | Search settings, duplicate results, run caps, and downstream delivery |
| ScrapeCreators | You want JSON inside your own worker or application | $47 buys 25,000 credits; search requests checked here charged one credit each | Your schedule, coverage checks, deduplication, storage, and notifications |
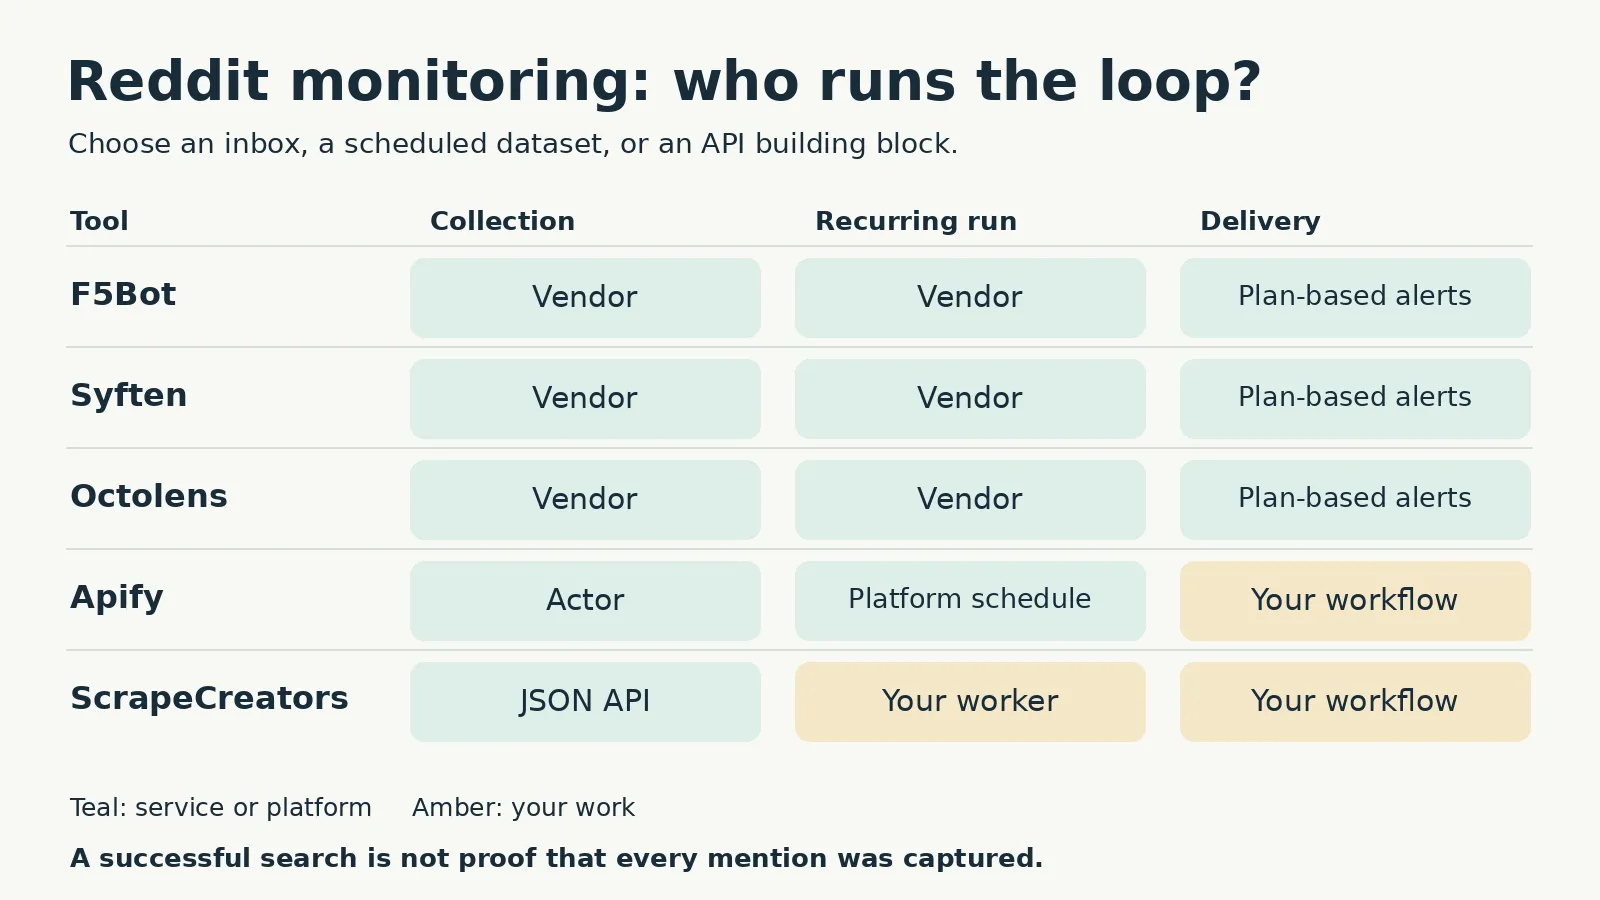
These are different purchases. An alert subscription includes work that an API request does not. A stored dataset result is not an email, a unique new mention, or an API page.
1. F5Bot for straightforward email alerts
F5Bot monitors Reddit submissions and comments, alongside Hacker News and Lobsters. It is a sensible starting point when the job is narrow: watch a few uncommon names and open useful conversations from your inbox.
The current plan grid matters more than an old recommendation calling it free for every founder. The free tier is personal use only, with five keywords, ten alerts per keyword per day, twenty daily alerts across the account, and delivery delayed by up to two hours. That is not an unlimited business monitoring plan.
Silver costs $9.99/month and raises the limits to twenty keywords, thirty daily alerts per keyword, and one hundred daily alerts overall. It includes keyword filtering and common-word support. Its listed alert delay is up to five minutes. F5Bot explicitly measures that delay from when it finds a match, not from when Reddit publishes it.
For a business that needs simple email alerts, I would evaluate Silver rather than quietly treating the personal free tier as a commercial offer. Slack and Discord start on Gold at $49.99/month. API access and webhooks start on Platinum at $214.99/month. They are not included with the cheapest paid plan.
There is a useful setup trap in the FAQ: to restrict an alert to chosen communities, use only-subreddit=news,worldnews. Adding only-reddit as well widens the match because those only- flags use an OR rule. This is exactly the kind of detail that can turn a quiet alert into an inbox problem.
Choose another option if you need an application-owned history, complicated qualification logic, or a shared workflow with integrations on an entry plan. Also check what happens at the daily caps. F5Bot says an over-limit keyword can be disabled and must be manually re-enabled.
2. Syften for precise community filters
Syften’s Reddit product focuses on finding public posts and comments with detailed rules. It supports restrictions by subreddit, author, title, and content type, alongside keyword and domain matching. That makes it worth evaluating when a common-word brand overwhelms a basic alert.
Its current pricing section lists Entry at $29.95/month with three community filters and one hundred community results per day. Standard is $49.95/month with twenty community filters and two hundred daily results. Standard also adds AI filtering and Slack. PRO is $119.95/month with one hundred community filters and five hundred daily results, plus webhooks and MCP.
Do not read three filters as three words without inspecting the syntax. A filter is a query, and its usefulness depends on what you can express in that query. The documentation is the place to check how your actual brand, exclusions, and source restrictions fit.
Syften targets Reddit delivery in under one minute. That is the vendor’s target, not a latency result from my test. Its archive and live monitoring are also different jobs. Entry lists seven days of archive search, Standard thirty days, and PRO the available source history without a plan-imposed time limit. Available history is not a promise that every old Reddit conversation exists in the archive.
I would choose Syften over a raw API when a person needs a filtered stream of relevant conversations, not another system to maintain. Choose another workflow if your main requirement is a custom data product, an exact historical dataset, or analytics that its alert workflow does not supply.
3. Octolens for a team listening workflow
Octolens combines Reddit post and comment monitoring with AI relevance scoring, sentiment, reporting, and delivery through Slack, email, API, and webhooks. It fits a team that wants to route mentions into existing work rather than maintain a collector.
The pricing page defaults to annual billing. Pro displays as $159/month billed annually. Switching to monthly changes it to $199/month. Both show ten keywords and 15,000 mentions. That distinction is easy to lose in a comparison table.
Pro lists an hourly refresh, even though the Reddit landing page also advertises mentions within one or two minutes. Scale lists real-time refresh, forty keywords, and 50,000 mentions, at $599/month billed monthly or $499/month billed annually. Ask which timing applies to your plan and source instead of assuming the fastest landing-page claim applies everywhere.
API, webhooks, and MCP appear on every public plan. That is a different access model from a service that reserves webhooks for its highest tier. Overage settings still matter: the pricing page says extra mentions can keep flowing and create additional charges. Set a spend cap or disable flex mentions if you need a hard budget.
Choose Octolens when several people need the same mention stream and reporting alongside it. It is harder to justify for one person watching two uncommon keywords. I have not verified the vendor’s relevance accuracy, complete subreddit coverage, or delivery times through a paid account.
4. Apify for scheduled search datasets
Reddit Scraper Lite by Trudax is a relevant Apify option when your monitoring job should produce saved datasets. Its inputs accept search terms or starting URLs, with sort and date controls. Apify provides scheduled Actor runs, so collection does not have to depend on your laptop staying open.
This is not the same purchase as a finished keyword-alert inbox. Decide how each run will identify unseen records, qualify matches, and deliver them. A dataset full of repeated posts is not a useful notification queue.
The Actor’s pricing tab lists result-stored events at $4.00 per 1,000 on Free, $3.80 on Starter, $3.60 on Scale, and $3.40 on Business. It also lists an Actor-start event of $0.02 per 1 GB. The headline “from $3.40” is the Business rate, not the default rate for every account. Confirm the selected plan and run’s charges before setting a frequent schedule.
The input documentation deserves a careful read. The README says search parameters are ignored when starting URLs are provided. It also separates searching for posts from fetching comments on those posts. Do not assume that collecting comments from matching threads is equivalent to finding keyword mentions in comments anywhere on Reddit.
Choose Apify if runs, datasets, exports, and platform scheduling are useful parts of your existing stack. Choose a dedicated alert service if you do not want to design the last mile. I reviewed this Actor’s current contract and prices; I did not execute it or compare its recall with the other tools.
5. ScrapeCreators for a monitoring loop you own
ScrapeCreators’ Reddit API is the building-block option. It returns structured search data. Your code decides when to search, what counts as new, which matches deserve attention, and where to send them.
For a marketer who only wants alerts, that is extra work. For an application that needs its own qualification rules and storage, it can be the reason to use an API.
On October 22, I checked these production requests:
| Request | Actual result | Boundary exposed |
|---|---|---|
query=notion&sort=new&timeframe=day&trim=true | Seven posts, then seven on the next cursor page; one credit per page | The ordinary word “notion” appears outside the software community |
query=notion&filter=comments&sort=new&trim=true | Ten comment records, one credit, with a continuation cursor | Comment search returns a different record shape from posts |
query=subreddit:Notion&sort=new&timeframe=day&trim=true | Seven posts, all in r/Notion, one credit | Some returned creation times were older than a strict rolling 24 hours |
| A deliberately nonexistent keyword | Empty successful page, one credit | An empty search can still cost a credit |
The two broad post pages had no overlapping IDs. More pages remained. None of these observations establishes complete coverage, a fixed page size, or an alert-latency guarantee.
The search docs describe the post search controls. During this check, the current backend and live API also supported filter=comments, but the generated reference’s parameter list omitted that filter. Confirm the live contract before depending on it; do not assume timeframe filters comments just because it exists for posts.
The current credit pricing is $47 for 25,000 credits, with pay-as-you-go credits that do not expire. Search is not a built-in push subscription. If you want to try the building block, create an account and evaluate your own keywords before building the notification layer.
A bounded monitoring preview
This Python example makes at most two post-search requests, enforces the subreddit and a rolling 24-hour cutoff locally, and deduplicates IDs. It prints candidates for review. It does not send messages, schedule itself, store a durable seen-ID set, or claim to collect every matching post.
import json
import os
import re
import time
import urllib.parse
import urllib.request

rows = {}
after = None
credits = 0
pages = 0
cutoff = time.time() - 24 * 60 * 60
for _ in range(2):
    params = {
        "query": "subreddit:Notion",
        "sort": "new",
        "timeframe": "day",
        "trim": "true",
    }
    if after:
        params["after"] = after
    request = urllib.request.Request(
        "https://api.scrapecreators.com/v1/reddit/search?"
        + urllib.parse.urlencode(params),
        headers={"x-api-key": os.environ["SCRAPE_CREATORS_API_KEY"]},
    )
    with urllib.request.urlopen(request, timeout=40) as response:
        data = json.load(response)
    if data.get("success") is not True or not isinstance(data.get("posts"), list):
        raise RuntimeError("Search did not return a usable post page")
    pages += 1
    credits += data.get("credits_charged", 0)
    for post in data["posts"]:
        if not post.get("id") or not post.get("url"):
            continue
        if post.get("subreddit", "").lower() != "notion":
            continue
        created = post.get("created_utc")
        if not isinstance(created, (int, float)) or created < cutoff:
            continue
        text = post.get("title", "") + " " + (post.get("selftext") or "")
        if re.search(r"\bnotion\b", text, re.IGNORECASE):
            rows[post["id"]] = {
                key: post.get(key)
                for key in ("id", "title", "subreddit", "url", "created_utc")
            }
    after = data.get("after")
    if not after:
        break
print(json.dumps({
    "pages_requested": pages,
    "credits_charged": credits,
    "has_more": bool(after),
    "candidates": list(rows.values()),
}, indent=2))
I ran that exact code on October 22. It used two credits and printed three candidate posts, with has_more: true. These were keyword candidates, not three qualified leads. The local time check also prevented older rows from becoming fresh alerts.
A production worker needs persistent IDs, an overlap window, bounded pagination with backlog detection, error reporting, and retry-safe delivery. Keep collection separate from delivery: mark an alert delivered only after your destination accepts it. If you need full discussion context, the separate Reddit comment-scraper comparison covers thread and reply collection. The broader Reddit scraper list covers extraction tools rather than monitoring services.
Compare the cost of the whole loop
For an API, frequency is part of the price. As a model, five keyword searches every fifteen minutes, one page each, for thirty days means 14,400 requests. At one credit each, that is 14,400 credits. At the $47-per-25,000-credit package ratio, the usage allocation is $27.07. You still buy the $47 package; this is not a $27.07 monthly subscription.
That model excludes extra pages, a separate comment-search pass, retries, hosting, storage, notifications, and optional AI scoring. Empty searches can still consume credits. Checking both posts and comments is not automatically one request.
For Apify, price the results stored across recurring runs and the start events, not just unique IDs in your final database. For subscription services, inspect caps and overages, the billing period, and whether the integration you need belongs to the displayed tier.
Evaluate relevance and delivery separately
A public discussion about noisy Reddit alerts asks a more useful question than which tool has the most AI features: how do you narrow the stream without discarding useful conversations? The replies include vendor promotion and repeated text, so I did not treat them as independent product endorsements.
A builder walkthrough and its comments also separate the visible dashboard from the underlying data source. Viewers asked how Reddit data was collected, and the creator described RSS in replies. That informed this article’s distinction between collection, qualification, and delivery. It does not prove RSS or any vendor is complete or suitable for your workload.
For a trial, label a small set of public conversations you actually want to find. Include a brand mention in a comment, a common-word false positive, an old thread with a new reply, and a relevant conversation without a product name. Then check:
- Did the tool find the post or the individual comment you expected?
- What is the publication time, first-seen time, and actual delivery time? Keep them separate.
- Did a cap, outage, relevance filter, or exhausted page budget hide a result?
- Did the same record create another alert on the next run?
- Can a person understand why the result matched and open its source?
Measure useful conversations reviewed, not just the count of alerts. Keep replies manual and appropriate to the community. This comparison is about listening, not an excuse to automate unsolicited promotion.
Frequently asked questions
What is the best free Reddit keyword monitoring tool?
F5Bot has a personal-use free tier for five keywords. It is a reasonable way to try email alerts within its caps and delay. Its current pricing does not present that tier as free commercial monitoring. A business should review a paid plan or another service’s terms.
Can Reddit keyword monitoring include comments?
Yes, but check the exact collection method. F5Bot, Syften, and Octolens describe post and comment monitoring. ScrapeCreators returned comment-search records in this run. Fetching comments beneath keyword-matched posts is a narrower job than searching for matching comments across Reddit.
Are Reddit keyword alerts real-time?
Not automatically. Search refresh, indexing delay, filtering, and notification delivery all contribute. F5Bot lists plan-specific delays after discovery; Syften publishes a delivery target; Octolens distinguishes hourly Pro refresh from real-time Scale. This article did not measure those promises.
Should I buy an alert service or build with an API?
Buy a service when you need useful notifications and do not want to operate the loop. Build when your application needs custom data ownership, matching rules, or routing, and someone will maintain it. A successful API request is only the collection step.