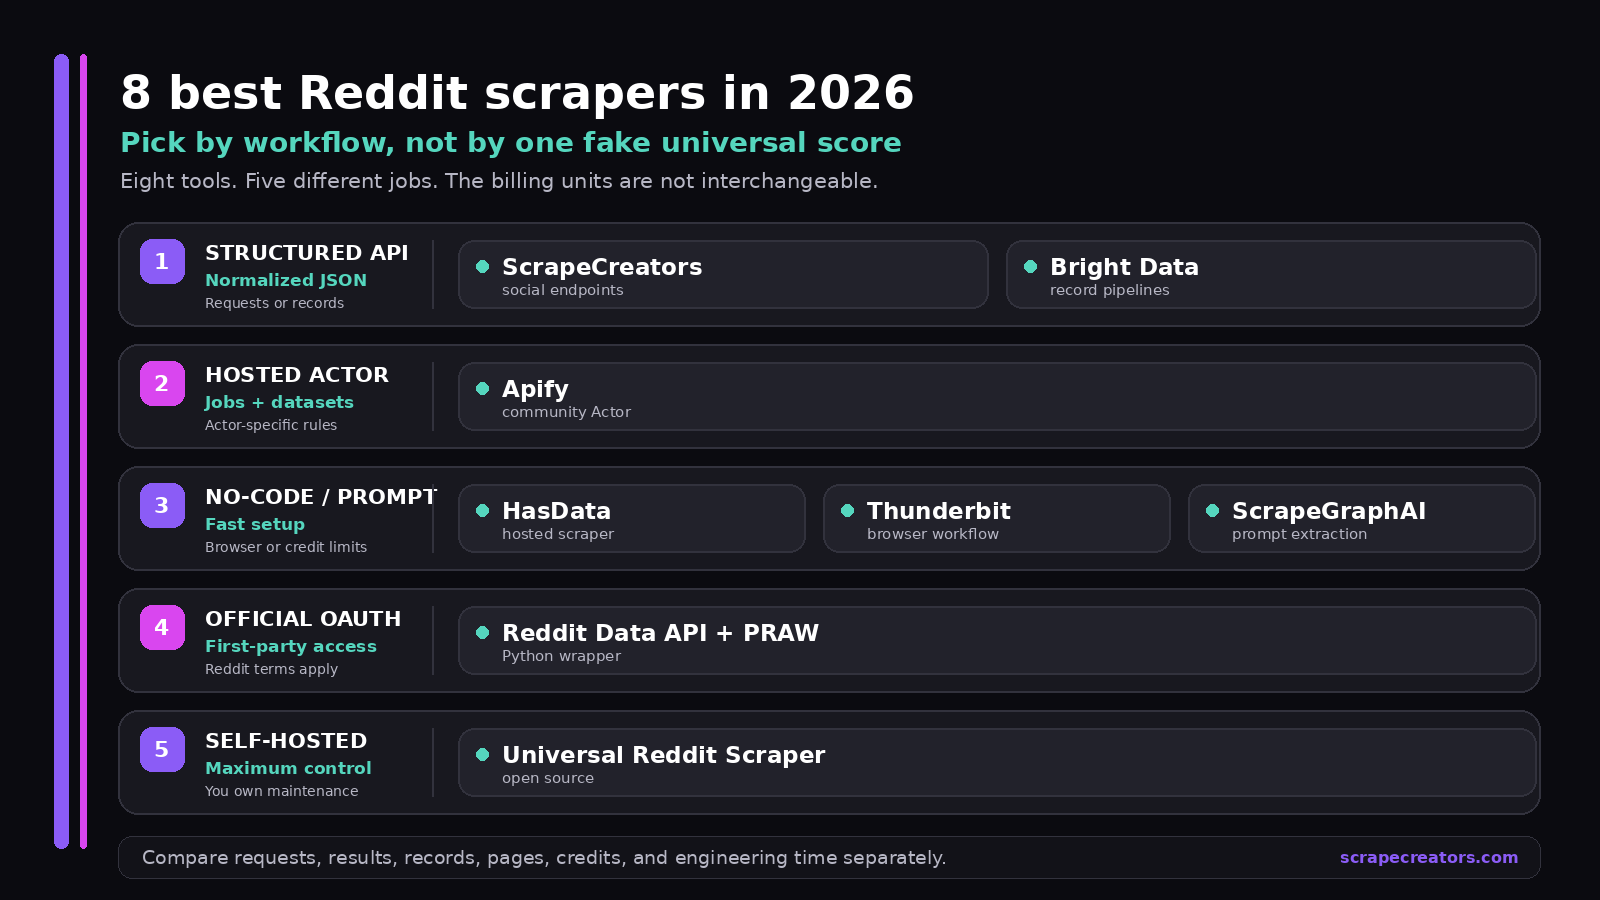
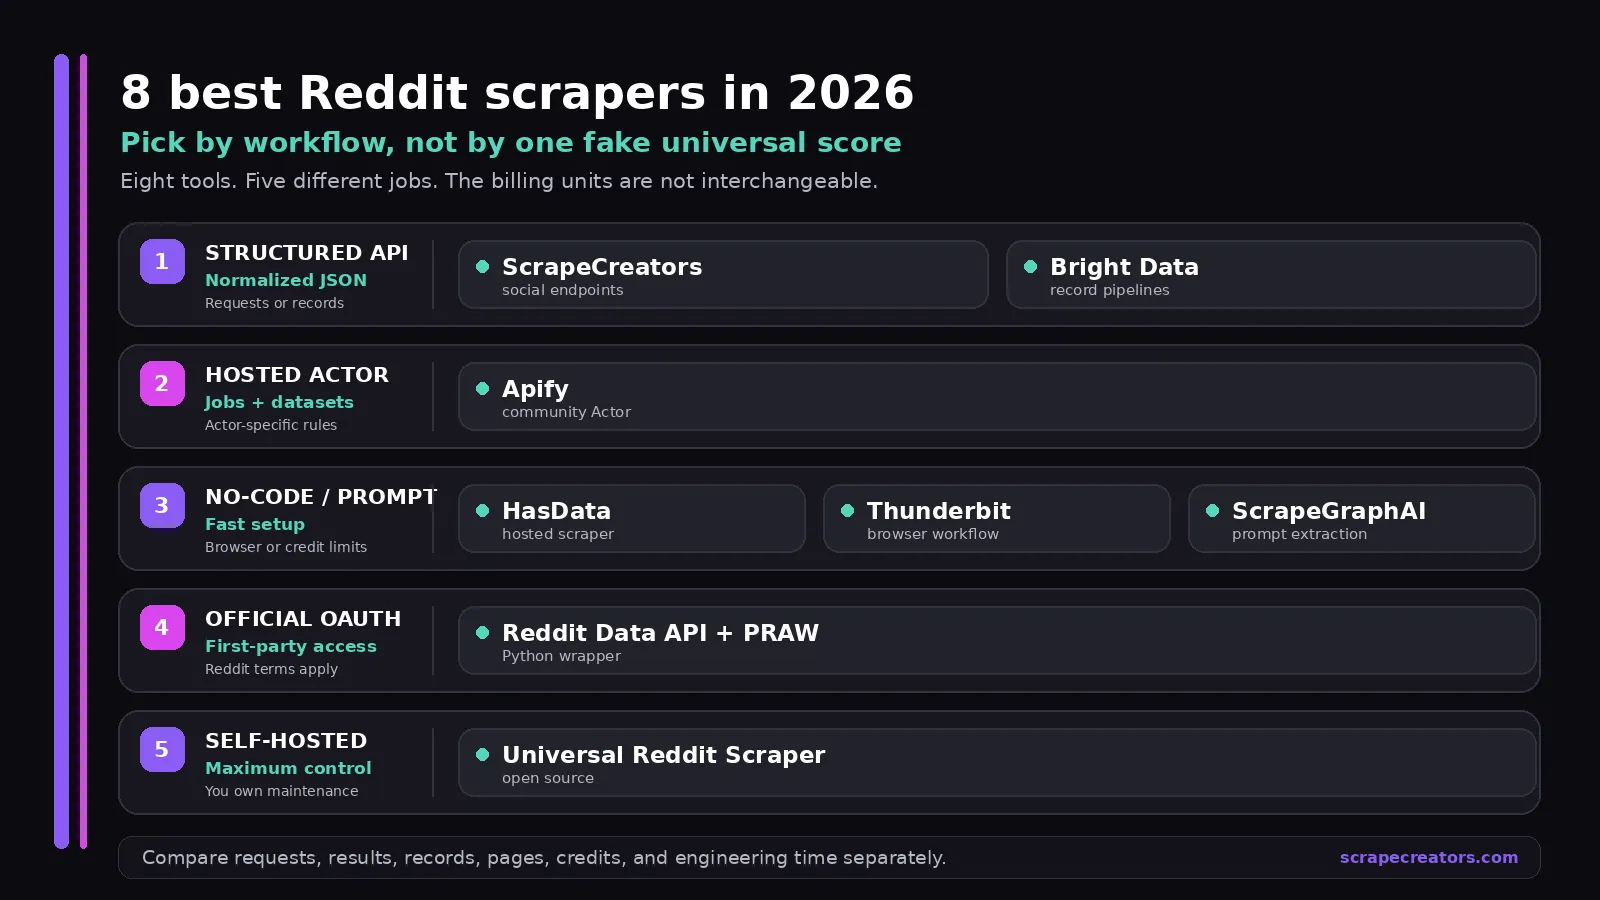
The best Reddit scraper depends on how you want to run it. Choose ScrapeCreators for a structured hosted API, Apify for an Actor and dataset workflow, Bright Data for record-based delivery, Thunderbit for a small no-code export, Reddit’s Data API with PRAW for approved first-party access, or a self-hosted project when you can own the maintenance. There is no honest universal winner because these tools sell different work.
I run ScrapeCreators, so my first-place recommendation comes with an obvious bias. I checked product and pricing facts against official sources on September 18, 2026. I also ran a live ScrapeCreators Reddit search request. I did not run a controlled benchmark across all eight products.
Quick comparison
| Rank | Reddit scraper | Choose it if | Public starting point checked September 18, 2026 | Main limitation |
|---|---|---|---|---|
| 1 | ScrapeCreators | You want structured public Reddit posts, comments, subreddits, and search behind one API | 100 free credits; $47 for 25,000 credits | It is a focused hosted API, not a browser or raw proxy product |
| 2 | Apify Reddit Scraper Lite | You want an Actor, runs, datasets, exports, schedules, and integrations | $5 of monthly platform usage free; this Actor lists $3.40 per 1,000 stored results | Community Actors have their own schemas, maintenance, and prices |
| 3 | Bright Data Reddit Scraper | You want managed scraper jobs and record delivery at larger scale | 5,000 free records per month; the page lists rates from $0.75 per 1,000 records | The record price is not the same unit as an API call or page |
| 4 | HasData Reddit Scraper | You want a hosted Reddit-specific scraper with API or CSV/JSON export | 1,000 free monthly API calls; paid pricing starts at $49 per month | Plans use rows and credits, so pagination and output size matter |
| 5 | Thunderbit Reddit Scraper | You want a browser extension and small no-code export | Free plan lists 6 pages per month; annual Starter displays as $9 per month | A browser workflow is harder to run as a reliable backend service |
| 6 | ScrapeGraphAI | You want prompt-based extraction that can work beyond Reddit | Free plan available; Starter is $20 per month | It is a general extractor, not a Reddit-specific object model |
| 7 | Reddit Data API with PRAW | You want the first-party API and can satisfy Reddit’s access terms | PRAW is open source; commercial API use may require a separate Reddit agreement | Access approval, OAuth, limits, and policy compliance stay with you |
| 8 | Universal Reddit Scraper | You want open-source code, Docker, and full operational control | MIT-licensed software; you pay for hosting, proxies, and maintenance | You own breakage, blocking, storage, and deployment |
These prices are not normalized. A request, stored result, record, row, browser page, platform credit, and hour of engineering are different units. Any table that turns them into one neat “price per scrape” number without a real test workload is making up precision.
How I ranked these tools
I used five questions instead of counting feature bullets:
- What does the buyer receive: Reddit objects, records, a rendered page, or code to operate?
- Can it collect the public posts, comments, search results, and subreddit data the buyer actually asked for?
- Does pagination expose a stable way to continue, or does the tool stop at a convenient first page?
- What creates the bill: requests, results, rows, pages, credits, compute, or your own infrastructure?
- Who fixes the scraper when Reddit changes a page or access rule?
The current US Google results for reddit scraper are unusually mixed. On September 18, 2026, the first page included Reddit discussions, a GitHub project, a Chrome extension, a Medium list, Bright Data documentation, an Apify Actor, and smaller dedicated tools. The best reddit scraper results added vendor roundups but kept Reddit threads and open-source projects near the top.
That mix is a clue. Searchers are not choosing between eight interchangeable SaaS dashboards. Some want a quick export. Some need a production API. Others want source code because they would rather fix it themselves than depend on a vendor.
1. ScrapeCreators for a structured Reddit API
Choose ScrapeCreators if: your application needs public Reddit posts, comments, subreddit feeds, search, or account data as JSON, and you do not want to maintain a Reddit parser.
Choose another tool if: you want to point a browser at arbitrary pages, run custom selectors, post to Reddit, access private data, or own the full crawler stack.
ScrapeCreators’ Reddit API exposes Reddit-specific endpoints instead of asking you to send an arbitrary URL to a generic page scraper. That matters when your code needs stable fields such as id, subreddit, title, selftext, score, num_comments, and created_utc.
The public pricing section listed 100 free credits and $47 for 25,000 credits when checked. Credits are pay as you go and do not expire. Most endpoints cost one credit, but you should check the current pricing table and the response’s credits_charged field rather than assuming every endpoint has the same cost. If the endpoint fits your fixture set, create an account and use the free credits on your own Reddit inputs first.
I ran this production request on September 18, 2026:
curl --get "https://api.scrapecreators.com/v1/reddit/search" \
  -H "x-api-key: $SCRAPE_CREATORS_API_KEY" \
  --data-urlencode "query=reddit scraper" \
  --data "filter=posts" \
  --data "sort=relevance" \
  --data "timeframe=all" \
  --data "trim=true"
It returned HTTP 200, seven post rows, and credits_charged: 1. This is an abbreviated object from the response:
{
  "success": true,
  "credits_charged": 1,
  "posts": [
    {
      "id": "1uf1upj",
      "subreddit": "scrapingtheweb",
      "title": "How to scrape Reddit??",
      "score": 10,
      "num_comments": 26,
      "url": "https://www.reddit.com/r/scrapingtheweb/comments/1uf1upj/how_to_scrape_reddit/"
    }
  ]
}
The Reddit Search API docs show the current filters and response. Use the Reddit post endpoint when you already have a permalink, and the subreddit endpoint for a community feed.
The limitation is scope. ScrapeCreators handles supported public Reddit objects. It does not give you a remote browser, a generic CSS selector engine, or a way to act as a logged-in Reddit user. The separate unofficial Reddit API guide explains the endpoint model and a basic implementation. This article owns the tool-selection question instead.
2. Apify for Actors and saved datasets
Choose Apify if: you want a hosted Actor with input schemas, runs, datasets, schedules, webhooks, and export formats already connected.
Choose another tool if: you want one vendor-maintained Reddit contract and predictable endpoint pricing without evaluating an individual Actor.
Reddit Scraper Lite is a community-maintained Actor. Its page says it can collect posts, comments, community metadata, and user profiles, with JSON, CSV, Excel, XML, and RSS output. The Actor currently lists $3.40 per 1,000 stored results. Apify’s free platform tier includes $5 of monthly usage.
That model is useful when the run itself is part of the product. You can start an Actor, let it fill a dataset, schedule it, and send the output elsewhere. It is a different abstraction from calling /v1/reddit/search inside a request path.
Read the Actor page as well as Apify’s platform page. The Reddit results also surface older or deprecated Actors. Authors can choose different inputs, output schemas, and prices. Check the maintenance badge, recent changes, sample output, issue history, and what counts as a stored result before building around one Actor.
3. Bright Data for record-based delivery
Choose Bright Data if: your team wants a managed Reddit scraper, batch delivery, and pricing expressed in records rather than maintaining collection infrastructure.
Choose another tool if: your application needs a lightweight request-response API with a small, platform-specific contract.
Bright Data’s Reddit Scraper API documentation appears in the live results for both reddit scraper and reddit scraping api. Its product page lists coverage for profiles, posts, subreddits, and comments, with delivery through API, webhook, and cloud storage.
The public page offered 5,000 free records per month and displayed prices starting at $0.75 per 1,000 records when checked. The useful unit is a delivered record. That can fit a batch pipeline well, but do not compare it directly with a per-request API until you know how many records your jobs return and which records count toward the bill.
Bright Data is the most infrastructure-heavy option in this list. That can be a strength for teams that already buy data collection at volume. It is probably excessive for a developer who needs one subreddit search in a product request.
4. HasData for a hosted Reddit scraper
Choose HasData if: you want a Reddit-specific hosted scraper with API access and downloadable JSON or CSV, but do not need a full Actor marketplace.
Choose another tool if: you need a wide catalog of Reddit endpoint shapes or want the scraper embedded in a browser workflow.
HasData’s Reddit scraper says it can extract posts, comments, votes, usernames, timestamps, and subreddit metadata. The page lists API and dashboard access, pagination, country targeting, and CSV/JSON output.
Its free plan currently lists 1,000 API calls and 1,000 rows per month. The first paid plan is $49 per month with 100,000 credits and 200,000 rows. Those two numbers are separate constraints. Estimate both request count and returned rows before deciding that the plan covers your workload.
HasData sits between a narrow endpoint API and a broader data collection platform. The public page is clear about output fields and export. I would put it on a trial list when CSV delivery matters as much as application integration.
5. Thunderbit for small no-code exports
Choose Thunderbit if: a person wants to collect a modest set of Reddit pages from the browser and export it without writing code.
Choose another tool if: the scraper has to run unattended behind your application, maintain a deep comment cursor, or meet a backend latency target.
Thunderbit’s Reddit template is a browser-extension workflow. You describe or select what to extract, run it on a Reddit page, and export the result to a spreadsheet-style destination.
The pricing page listed 6 pages per month on the free plan. With annual billing selected, Starter displayed as $9 per month for 5,000 credits per year. A page and a Reddit object are not the same thing. A long comment thread, a search result, and 20 individual post pages can create very different browser work.
This is the easiest category to misuse. No-code is a good fit for a small manual export. It does not automatically become a reliable data service because the first run worked in your browser.
6. ScrapeGraphAI for prompt-based extraction
Choose ScrapeGraphAI if: you want a general prompt-driven extractor that can work on Reddit and other websites, and you value flexible page extraction over a fixed Reddit schema.
Choose another tool if: you need Reddit-native pagination, comments, post relationships, or a stable object contract that is identical on every call.
ScrapeGraphAI’s own best Reddit scraper roundup ranked on the live best reddit scraper results when checked. Its product is broader than the article title suggests. You send URLs or a crawl target and describe the output you want. That is useful for irregular pages and one-off extraction.
The pricing page listed a free plan and a $20 per month Starter plan. It also publishes credit costs by operation. The basic Extract operation starts at five credits before options such as stealth mode. Check the current operation table because one prompt is not automatically one credit.
The trade-off is schema ownership. Prompt extraction can adapt quickly, but your application still needs a contract. Validate types, missing fields, duplicate comments, and pagination rather than accepting plausible JSON because it looks clean.
7. Reddit Data API and PRAW for first-party access
Choose Reddit’s Data API with PRAW if: first-party access is a requirement, your use case fits Reddit’s policies, and you can obtain and maintain the required OAuth credentials.
Choose another tool if: you cannot get the needed access, need a vendor to operate collection, or want one API across several social platforms.
PRAW is a Python wrapper for Reddit’s API. Its current documentation is for version 8.0.3 and describes authenticated and read-only clients, submissions, comments, subreddits, and streams. The library is open source, but the data access is still Reddit’s.
Reddit’s Data API Terms say developers may not use the API beyond the limits in its developer documentation without approval. The same terms say commercial use requires a separate agreement unless Reddit authorizes it in writing. That is why I would not call the official API simply “free” for every production business.
This route gives you the cleanest first-party relationship when Reddit approves the use. It also leaves OAuth, application review, rate limits, storage rules, and ongoing policy compliance with your team.
8. Universal Reddit Scraper for self-hosting
Choose Universal Reddit Scraper if: you want source code, Docker deployment, and permission to change the crawler yourself.
Choose another tool if: you expect a vendor to handle blocks, page changes, retries, monitoring, and support.
Universal Reddit Scraper is an MIT-licensed project with a CLI, REST API, Docker setup, multiple output formats, and optional proxy support. The repository presents it as a scraper for subreddits and users without Reddit API credentials.
The software price is $0. The operating cost is not. You still need compute, storage, monitoring, and possibly proxies. More importantly, you need someone who can tell the difference between an empty subreddit and an upstream block page that happened to return HTTP 200.
Open source makes sense when Reddit collection is important enough to own. It is a poor bargain when the project only needs data and nobody has time to maintain the path that gets it.
What builders asked for in public
I searched YouTube in a US context for reddit scraper and three close variants through ScrapeCreators. The four requests returned 80 rows and 57 unique video IDs. I read eight available English transcripts, then reviewed 108 top/new comment rows. After deduplication, that was 55 unique top-level comments plus 44 reply rows fetched from the reply endpoint.
I also searched Reddit, TikTok, and LinkedIn for the same four variants. After deduplication, I reviewed 11 Reddit posts, 32 Reddit comments, 73 TikTok videos, and 29 LinkedIn posts. These are qualitative samples, not a survey and not proof of Google demand.
Three questions kept changing what belonged in this comparison:
- People asked how many posts a tool could collect, whether a date range worked, and how to continue after the first page. That is why pagination and output units matter more here than a long feature list.
- Comments on tutorials asked about API access, changing Reddit behavior, comment limits, and export to analysis tools. That is why the official API and self-hosted lanes cannot be collapsed into one “free” option.
- No-code and AI workflow posts focused on monitoring mentions, finding customer pain, and sending results into another system. That is why I separated one-off browser exports from production APIs and scheduled datasets.
Two public Reddit discussions capture the split well. One builder wanted an alternative after public JSON, PRAW, browser automation, and a paid Actor each created a different problem. Another wanted a scraper that could understand a business description and surface relevant discussions. Those are not the same product request.
Run a Reddit scraper evaluation that tells you something
Use your real inputs. A clean demo subreddit proves very little.
Build a fixture set with at least:
- one active public subreddit;
- one small or nearly empty subreddit;
- old and new posts;
- a post with hundreds of comments and nested replies;
- deleted users and removed content;
- a keyword search with expected relevant results;
- a nonexistent permalink;
- two pagination steps, checked for duplicates.
Record HTTP status, latency, complete records, empty results, duplicates, cursor behavior, and the unit charged. Keep public counters separate from rows actually delivered. A post saying it has 500 comments does not mean the scraper returned 500 comment rows.
Then calculate:
usable cost = subscription + usage + hosting + retry cost + engineering time
cost per usable record = usable cost / complete deduplicated records
This is also where the best social media scraping APIs comparison helps. It explains why a social object API and a general web scraper belong in different evaluation lanes. If Apify is on your shortlist, the Apify vs ScrapeCreators guide goes deeper on Actors versus one endpoint catalog.
Limitations and legal boundaries
Public does not mean consequence-free. Check Reddit’s current terms, your legal basis, privacy obligations, and the rules that apply to your use case. Minimize collection. Do not collect private or restricted data. Do not use a scraper to bypass access controls, impersonate users, harass people, or build prohibited profiles.
Every option can return partial or stale data. Reddit deletes posts, hides or collapses comments, removes authors, changes pages, and applies access controls. A vendor can reduce maintenance, but no vendor can promise that every public object will remain available forever.
My recommendation is narrow. ScrapeCreators is the first tool I would try for a product that needs structured public Reddit data and does not want scraper maintenance. It is not the best choice for official first-party access, arbitrary browser automation, private data, posting actions, or teams that insist on owning the crawler.
Sources checked
Product, policy, and pricing pages checked September 18, 2026:
- ScrapeCreators Reddit API, docs, and pricing
- Apify Reddit Scraper Lite and Apify pricing
- Bright Data Reddit Scraper and Reddit scraper documentation
- HasData Reddit Scraper
- Thunderbit Reddit template and pricing
- ScrapeGraphAI and pricing
- Reddit Data API Terms and PRAW documentation
- Universal Reddit Scraper
- Public research examples: YouTube Reddit scraping tutorial, Apify Reddit scraper video, and Reddit discussion about current scraping options