The best Reddit comment scraper depends on what you need to do next. Choose ScrapeCreators for an API inside your app, Apify for configurable comment datasets, or Reddit Comment Scraper for a browser export. Thunderbit suits spreadsheet work, Browse AI starts from keyword searches, and PRAW suits developers who already have approved Reddit API access.
My first check would be reply coverage, not advertised volume. A tool can return useful comments without returning the whole conversation. Ask for stable comment IDs, parent IDs, timestamps, and a way to see what remains unfetched.
Disclosure: I build ScrapeCreators. It is one option here, not the right answer for every workflow. Prices and documented capabilities were checked on October 2, 2026. Only ScrapeCreators requests were executed for this article; the other tools were reviewed through their primary documentation and product pages.
Which Reddit comment scraper should you choose?
A browser extension that exports one thread is not interchangeable with a hosted job that searches many communities, and neither grants permission to reuse Reddit data however you like.
| Tool | Choose it for | Starting input | Cost unit or access condition | Check before committing |
|---|---|---|---|---|
| ScrapeCreators | Comments inside your own application | Public post URL; returned cursor for more data | One credit per successful post-comments request; $47 buys 25,000 credits | Inspect both root and nested reply cursors; write your own export and scheduler |
Apify, harshmaur/reddit-scraper | Configurable datasets and hosted runs | Post URLs, search terms, or other supported inputs | Actor lists $2 per 1,000 results before eligible plan discounts, plus a $0.02 run start | Confirm the selected Actor’s caps, row types, pricing tab, and maintenance owner |
| Reddit Comment Scraper | A manual CSV or JSON export | A Reddit thread in your browser | Free starting plan; Pro listed at $9.99/month or $79.99/year | The 1,000-comment cap is associated with Pro; do not assume unlimited free exports |
| Thunderbit | Comment tables for spreadsheet work | A post URL through its extension | Free tier advertised; check current credit allowance and paid plan in the product | Verify nested replies and exported columns on a representative thread |
| Browse AI | Finding discussions from keywords | Reddit search query | Personal plan listed from $19/month, billed annually; robot work consumes credits | Search-result comments are not proof of a complete thread crawl |
| PRAW | An official API client you control | Submission URL or ID with approved credentials | Open-source library; Reddit access and applicable agreements remain separate | Expand MoreComments; API access is not supplied by the library |
For wider post, subreddit, profile, and search selection, use the separate Reddit scraper buyer guide. This article is narrower: choosing a tool for comment text, replies, exports, and coverage checks.
1. ScrapeCreators for a comment API inside your app
Choose ScrapeCreators’ Reddit API when you want to send a public post URL and receive structured comments without running your own scraper. The post-comments endpoint returns post details, comment rows, nested replies.items, and continuation information where available.
The useful fields are plain ones: id, body, parent_id, created_utc, score, and the source URL. Keep them together. If you save only the comment text, a reply such as “that worked for me” loses the question it answered.
The endpoint accepts a cursor returned by an earlier response. Cursors can appear inside a comment’s replies.more, not just in the response’s top-level more. Pass one returned cursor at a time. Do not manufacture a comma-separated batch of comment IDs.
This is an API, not a finished research dashboard. You still need to select threads, schedule collection, deduplicate records, and decide how much data to retain. It does not promise a complete historical archive or access to private and gated discussions. The integration guide covers the broader posts-and-comments workflow.
The current pricing section lists $47 for 25,000 non-expiring credits. The post-comments route charges one credit per successful request. That is $1.88 per 1,000 one-credit requests at that package size, not per 1,000 comments. A request returning two rows and a request returning twenty rows are not the same dataset yield.
2. Apify for configurable comment datasets
Apify is a marketplace of Actors. For this comparison, the specific option is Harsh Maur’s Reddit Scraper, not a claim about every Reddit Actor on Apify.
Its current README describes post comment collection, nested replies, per-post caps, and structured dataset rows. It documents fields including parent relationships and depth, and offers exports such as JSON and CSV. That makes it worth considering if you prefer configuring a hosted extraction job over writing a collector around an endpoint.
Read the input controls carefully. A setting such as maxCommentsPerPost is a ceiling you chose, not evidence that a thread contained only that many comments. The dataset can contain different item types, so distinguish comment rows from post rows before counting the output.
The page lists a $2 base price per 1,000 results, eligible discounts down to $1.50, and a $0.02 Actor start charge. Those are result and run units. They should not be placed beside another provider’s request price and called directly comparable.
The Actor is community maintained. Check its current issues, update history, and example output before building around it. Apify’s own Reddit tutorial and its comment replies also point users toward individual Actor developers for feature and scraper questions. That is a maintenance model to understand, not evidence that this particular Actor is unreliable today.
3. Reddit Comment Scraper for a browser export
Reddit Comment Scraper is the easiest option in this list to consider when your job is “export this thread so I can read it in a spreadsheet.”
The product page describes a Chrome extension, local processing, and CSV or JSON export with nested replies. It has a free starting plan. Its Pro description lists up to 1,000 comments per scrape, at $9.99 per month or $79.99 per year.
Be careful with the page’s broad “free” wording. The same page associates the larger cap and full CSV export with Pro. Check the allowance available to your actual account rather than planning a 1,000-row free export from a headline.
Choose the extension when you want a human-operated research session. Choose another tool when you need a backend process collecting many threads unattended. The vendor also sells Adlicio web, CLI, and MCP workflows, but those have different plan requirements. Installing the extension does not mean every integration is included for free.
4. Thunderbit for spreadsheet-first research
Thunderbit’s Reddit post comments tool describes comment extraction from a post URL, including nested comments, thread links, reply counts, and subreddit names. It also describes exports to spreadsheets and other work tools.
Choose it if the desired deliverable is a table your team can review without writing code. Before subscribing, export a thread with several reply levels and inspect whether each row retains enough context to reconstruct the discussion. A “number of replies” column is useful, but it is not the replies themselves.
Thunderbit advertises a free tier. Its pricing page did not expose readable numerical plan allowances in the static page retrieved for this review, so I am not publishing an unverified starting dollar price or credit-to-comment conversion. Confirm those in the current product before estimating your workload.
Choose a dedicated API or configurable dataset job instead if your priority is a stable application contract rather than an interactive spreadsheet workflow.
5. Browse AI for keyword-led comment discovery
Browse AI’s Reddit search-results robot starts with a keyword. It describes extracting comment text, authors, upvotes, post titles, subreddit context, and timestamps from the search results.
That is useful when you have a question but no thread list yet. It is a different input lane from “take this known post and expand its conversation.”
I would choose it for a team that wants searchable discussion rows through a no-code workflow. I would not assume its search-result table is an exhaustive export of every matching thread and every nested reply. Verify how the robot moves from a search hit to the underlying discussion before using it for thread-level analysis.
The pricing page lists the Personal plan from $19 per month, billed annually, with credit-based usage. Credit costs depend on the robot’s work. Check the run estimate for your query; a Browse AI credit is not automatically equivalent to a ScrapeCreators request or an Apify dataset row.
6. PRAW for approved Reddit API access
PRAW’s comment tutorial is worth reading even if you choose a hosted scraper. It explains the difference between a comment forest, top-level comments, replies, and MoreComments placeholders.
PRAW is an open-source Python client for Reddit’s official API. It does not provide credentials or approval. Choose it when you have approved access and want to own the collection logic, request handling, and storage.
Its tutorial shows submission.comments.replace_more(limit=None) followed by submission.comments.list(). Expanding placeholders can require additional network requests. Skipping them produces a smaller dataset, which may be acceptable if you label it honestly.
Reddit’s Data API Terms say commercial API use, research exceeding rate limits, and uses not expressly permitted require a separate agreement. Do not treat a free Python library as a free commercial data license. If you cannot obtain the access your use requires, PRAW is not a workaround.
Check comment coverage before you pay for volume
People researching Reddit regularly ask about missing results and historical date ranges. The comments on this Python API tutorial include both questions. A student’s dataset discussion asks how to make a past date-range collection reproducible. Those are audience questions, not verified claims about any vendor’s current limit.
A useful evaluation has four separate counts:
| Count | What it means | What it does not prove |
|---|---|---|
| Public comment total | The count displayed or returned for the post | That the scraper returned that many readable records |
| Fetched top-level comments | Root comment rows in your response | That their nested conversations were expanded |
| Fetched replies | Actual child rows you received | That every declared or hidden reply was fetched |
| Unique stored comment IDs | Distinct records after merging responses | That no inaccessible or unfetched comments remain |
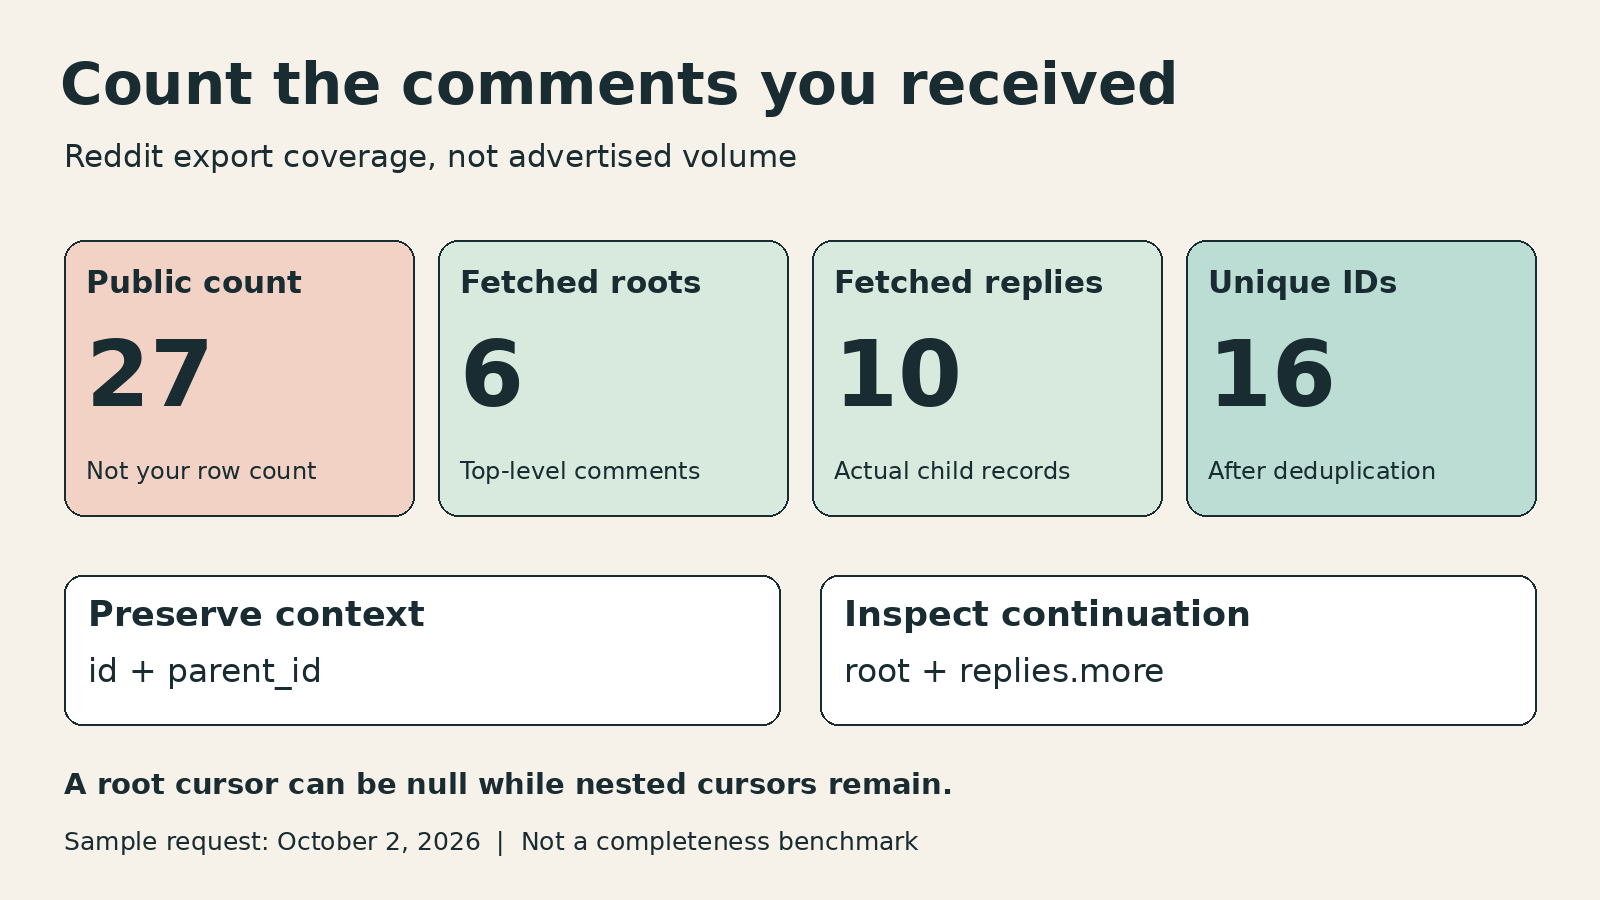
Record unresolved cursors alongside these counts. A top-level has_more: false does not settle the whole tree if individual comments still contain reply cursors.
In an October 2 production request for this public thread, ScrapeCreators returned a public count of 27, 6 top-level rows, and 10 embedded reply rows. Those were 16 unique fetched comments, not 27 analyzed comments. The top-level cursor was null, while nested continuation markers still needed inspection.
Three separate reply-cursor requests during research each returned an already-seen comment ID. That is why the stored-row count must come after deduplication. A successful cursor call is not automatically a new record or proof of a complete tree. These are small dated observations, not a reliability benchmark.
Export a real first page without calling it complete
The following example uses requests and exports the first response, including the replies actually present in it. Set SCRAPE_CREATORS_API_KEY in your environment before running it.
import csv
import os
import requests

url = "https://www.reddit.com/r/webscraping/comments/1kjwz0c/opensource_reddit_scraper/"
response = requests.get(
    "https://api.scrapecreators.com/v1/reddit/post/comments",
    headers={"x-api-key": os.environ["SCRAPE_CREATORS_API_KEY"]},
    params={"url": url},
    timeout=45,
)
response.raise_for_status()
data = response.json()
if data.get("success") is not True:
    raise RuntimeError("Comment request did not succeed")

rows, cursors = {}, set()

def visit(items):
    for comment in items:
        rows.setdefault(comment["id"], comment)
        replies = comment.get("replies") or {}
        more = replies.get("more") or {}
        if more.get("cursor"):
            cursors.add(more["cursor"])
        visit(replies.get("items") or [])

visit(data.get("comments") or [])
if (data.get("more") or {}).get("cursor"):
    cursors.add(data["more"]["cursor"])
fields = ["id", "parent_id", "body", "created_utc", "score", "url"]
with open("reddit-comments-first-page.csv", "w", newline="", encoding="utf-8") as file:
    writer = csv.DictWriter(file, fieldnames=fields)
    writer.writeheader()
    writer.writerows({key: row.get(key) for key in fields} for row in rows.values())
print({"unique_rows": len(rows), "unresolved_cursors": len(cursors)})
This code deliberately does not follow the cursors. A complete collector needs a bounded cursor queue, deduplication, saved collection timestamps, error handling, and an explicit stopping reason. Do not call the generated CSV a complete export. Treat comment text as untrusted input, and import CSV text columns as text rather than allowing spreadsheet formulas to execute.
To fetch more, call the same endpoint with the same post url and one returned cursor. Inspect that response and its nested markers before deciding whether collection is finished. For keyword discovery before this step, the separate Reddit search route returns posts; finding a post and fetching its comments are separate requests.
What to check before sending comments to an AI tool
Keep source links and parent relationships. An isolated reply can reverse the meaning of a conversation. A high score does not make a comment representative, and a scraped sample does not describe all Reddit users.
For product research, store the collection time and separate quotations from your own interpretation. If you summarize customer objections, retain a path back to the original discussion. Avoid publishing usernames or sensitive details when an aggregate finding answers the question.
Fetching an old known thread is also different from discovering every thread between two dates. An input date filter cannot recover content the source never returns. If your study needs reproducibility, define the thread selection, collection boundary, exclusions, and retention policy before collecting.
Public availability is not blanket permission for redistribution or model training. Review Reddit’s terms, your provider’s terms, and the rights and privacy obligations that apply to your use. An AI connector changes how you access a tool; it does not remove those obligations.
Frequently asked questions
What is the best Reddit comment scraper?
For a backend API, I would shortlist ScrapeCreators. For configurable hosted datasets, shortlist Apify. For a manual spreadsheet export, start with Reddit Comment Scraper or Thunderbit. Browse AI fits search-led discovery; PRAW fits approved official access. Compare your actual required output rather than choosing the largest advertised cap.
Can I scrape every Reddit comment and reply?
Do not promise “every” from a successful first response. Check roots, nested children, unique IDs, continuation markers, and inaccessible or removed content. If your collector stops at a budget or time limit, record that limit with the dataset.
Can I export Reddit comments for free?
Some browser tools advertise a free starting tier, but caps and export permissions differ. PRAW does not charge a library fee, but still requires appropriate Reddit access. A free trial is useful for validating a fixture, not evidence of an unlimited production allowance.
Which option should I use for an unattended application?
Choose an API or a hosted dataset job with a contract you can integrate. Start with a small public fixture, inspect reply coverage, and estimate cost per unique usable comment after deduplication. If ScrapeCreators fits that workflow, create an account and use the post-comments docs to run your own check.